01
模型评测
LLM、VLM、AIGC、RAG 任务,具备样本 review、Judge 契约、语义版本与可携带产物。
开源 AI 评测基础设施
一条可追溯的证据路径,覆盖 LLM、VLM、Agent、评测集、压测与每个决策背后的产物。
evalscope eval \
  --model your-model --eval-type openai_api \
  --api-url https://api.example.com/v1 \
  --api-key "$MODEL_API_KEY" \
  --datasets gsm8k --limit 5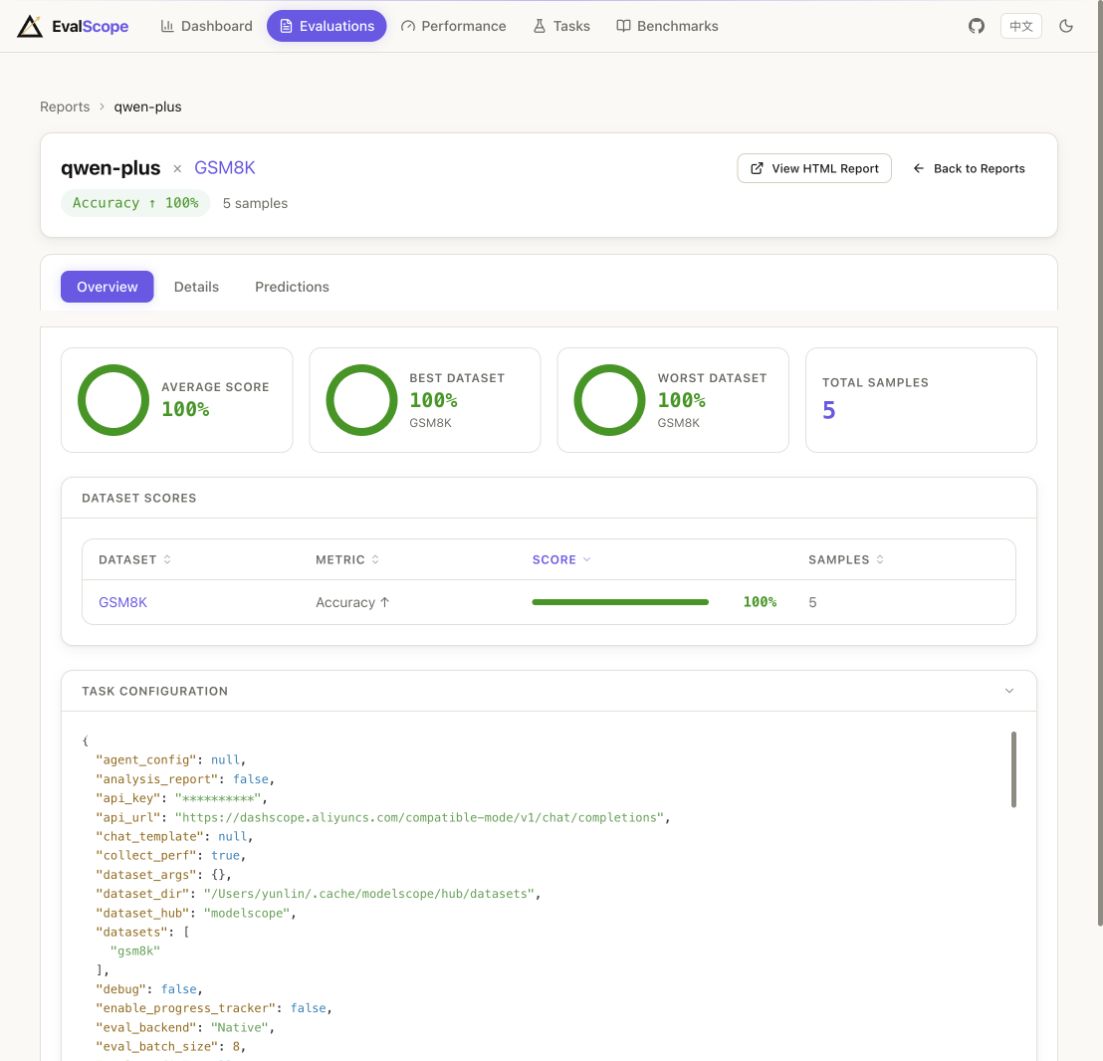
一个系统,三种测量视角
LLM、VLM、AIGC、RAG 任务,具备样本 review、Judge 契约、语义版本与可携带产物。
跨原生 Agent 评测和外部 Harness 工作流,测量请求、工具、token 与最终结果。
将并发、延迟、RPS、TTFT 与吞吐转化为可复现的服务决策。
证据,而非单一分数
输入、预测、review、报告、配置和版本化 metadata 彼此关联,结果可被审查,而不只是重复运行。
已录制的 CLI 运行
$ evalscope eval \
--model qwen-plus \
--eval-type openai_api \
--api-url https://dashscope.aliyuncs.com/compatible-mode/v1 \
--api-key "$DASHSCOPE_API_KEY" \
--datasets gsm8k arc --limit 5 --seed 42 \
--generation-config stream=True \
--work-dir outputs/website-terminal-demo
2026-09-11 10:32:18 - evalscope - INFO: Args: Task config is provided with CommandLine type.
2026-09-11 10:32:19 - evalscope - INFO: Running with native backend
2026-09-11 10:32:19 - evalscope - INFO: Dump task config to outputs/website-terminal-demo/20260911_103219/configs/task_config.yaml
"generation_config": {"batch_size": 8, "stream": true}
2026-09-11 10:32:19 - evalscope - INFO: Start loading benchmark dataset: gsm8k
2026-09-11 10:32:19 - evalscope - WARNING: gsm8k: 5 samples to evaluate (1 subset, --limit=5 per subset).
2026-09-11 10:32:19 - evalscope - INFO: Subsets of gsm8k: ['main']
2026-09-11 10:32:19 - evalscope - INFO: Loading model for prediction...
Running[eval]: 0%| | 0/2 [00:00<?, ?benchmark/s]
2026-09-11 10:32:25 - evalscope - INFO: Evaluating[gsm8k] 100%| 5/5 [Elapsed: 00:06 < Remaining: 00:00]
2026-09-11 10:32:25 - evalscope - INFO: gsm8k report table:
┌───────────┬───────────┬────────────┬──────────┬───────┬─────────┐
│ Model     │ Dataset   │ Metric     │ Subset   │   Num │ Score   │
├───────────┼───────────┼────────────┼──────────┼───────┼─────────┤
│ qwen-plus │ GSM8K     │ Accuracy ↑ │ main     │     5 │ 100%    │
└───────────┴───────────┴────────────┴──────────┴───────┴─────────┘
2026-09-11 10:32:25 - evalscope - INFO: gsm8k perf table:
Model      Dataset      Num  Avg Lat    Avg TTFT    Avg TPOT    Avg Thpt       Avg In    Avg Out
---------  ---------  -----  ---------  ----------  ----------  -----------  --------  ---------
qwen-plus  GSM8K          5  3.768 s    587.2 ms    17.9 ms     49.62 tok/s       659        187
2026-09-11 10:32:25 - evalscope - INFO: Start loading benchmark dataset: arc
2026-09-11 10:32:25 - evalscope - WARNING: arc: 10 samples to evaluate (2 subsets, --limit=5 per subset).
2026-09-11 10:32:25 - evalscope - INFO: Subsets of arc: ['ARC-Easy', 'ARC-Challenge']
2026-09-11 10:32:26 - evalscope - INFO: Evaluating[arc] 100%| 10/10 [Elapsed: 00:01 < Remaining: 00:00]
2026-09-11 10:32:26 - evalscope - INFO: arc report table:
┌───────────┬───────────┬────────────┬───────────────┬───────┬─────────┐
│ Model     │ Dataset   │ Metric     │ Subset        │   Num │ Score   │
├───────────┼───────────┼────────────┼───────────────┼───────┼─────────┤
│ qwen-plus │ ARC       │ Accuracy ↑ │ ARC-Easy      │     5 │ 100%    │
├───────────┼───────────┼────────────┼───────────────┼───────┼─────────┤
│ qwen-plus │ ARC       │ Accuracy ↑ │ ARC-Challenge │     5 │ 80%     │
├───────────┼───────────┼────────────┼───────────────┼───────┼─────────┤
│ qwen-plus │ ARC       │ Accuracy ↑ │ OVERALL       │    10 │ 90%     │
└───────────┴───────────┴────────────┴───────────────┴───────┴─────────┘
2026-09-11 10:32:26 - evalscope - INFO: arc perf table:
Model      Dataset      Num  Avg Lat    Avg TTFT    Avg TPOT    Avg Thpt      Avg In    Avg Out
---------  ---------  -----  ---------  ----------  ----------  ----------  --------  ---------
qwen-plus  ARC           10  0.496 s    400.8 ms    31.8 ms     8.06 tok/s       116          4
2026-09-11 10:32:27 - evalscope - INFO: HTML report generated: outputs/website-terminal-demo/20260911_103219/reports/report.html
2026-09-11 10:32:27 - evalscope - INFO: Finished evaluation for qwen-plus on ['gsm8k', 'arc']
2026-09-11 10:32:27 - evalscope - INFO: Output directory: outputs/website-terminal-demo/20260911_103219
AGENT 与 HARNESS
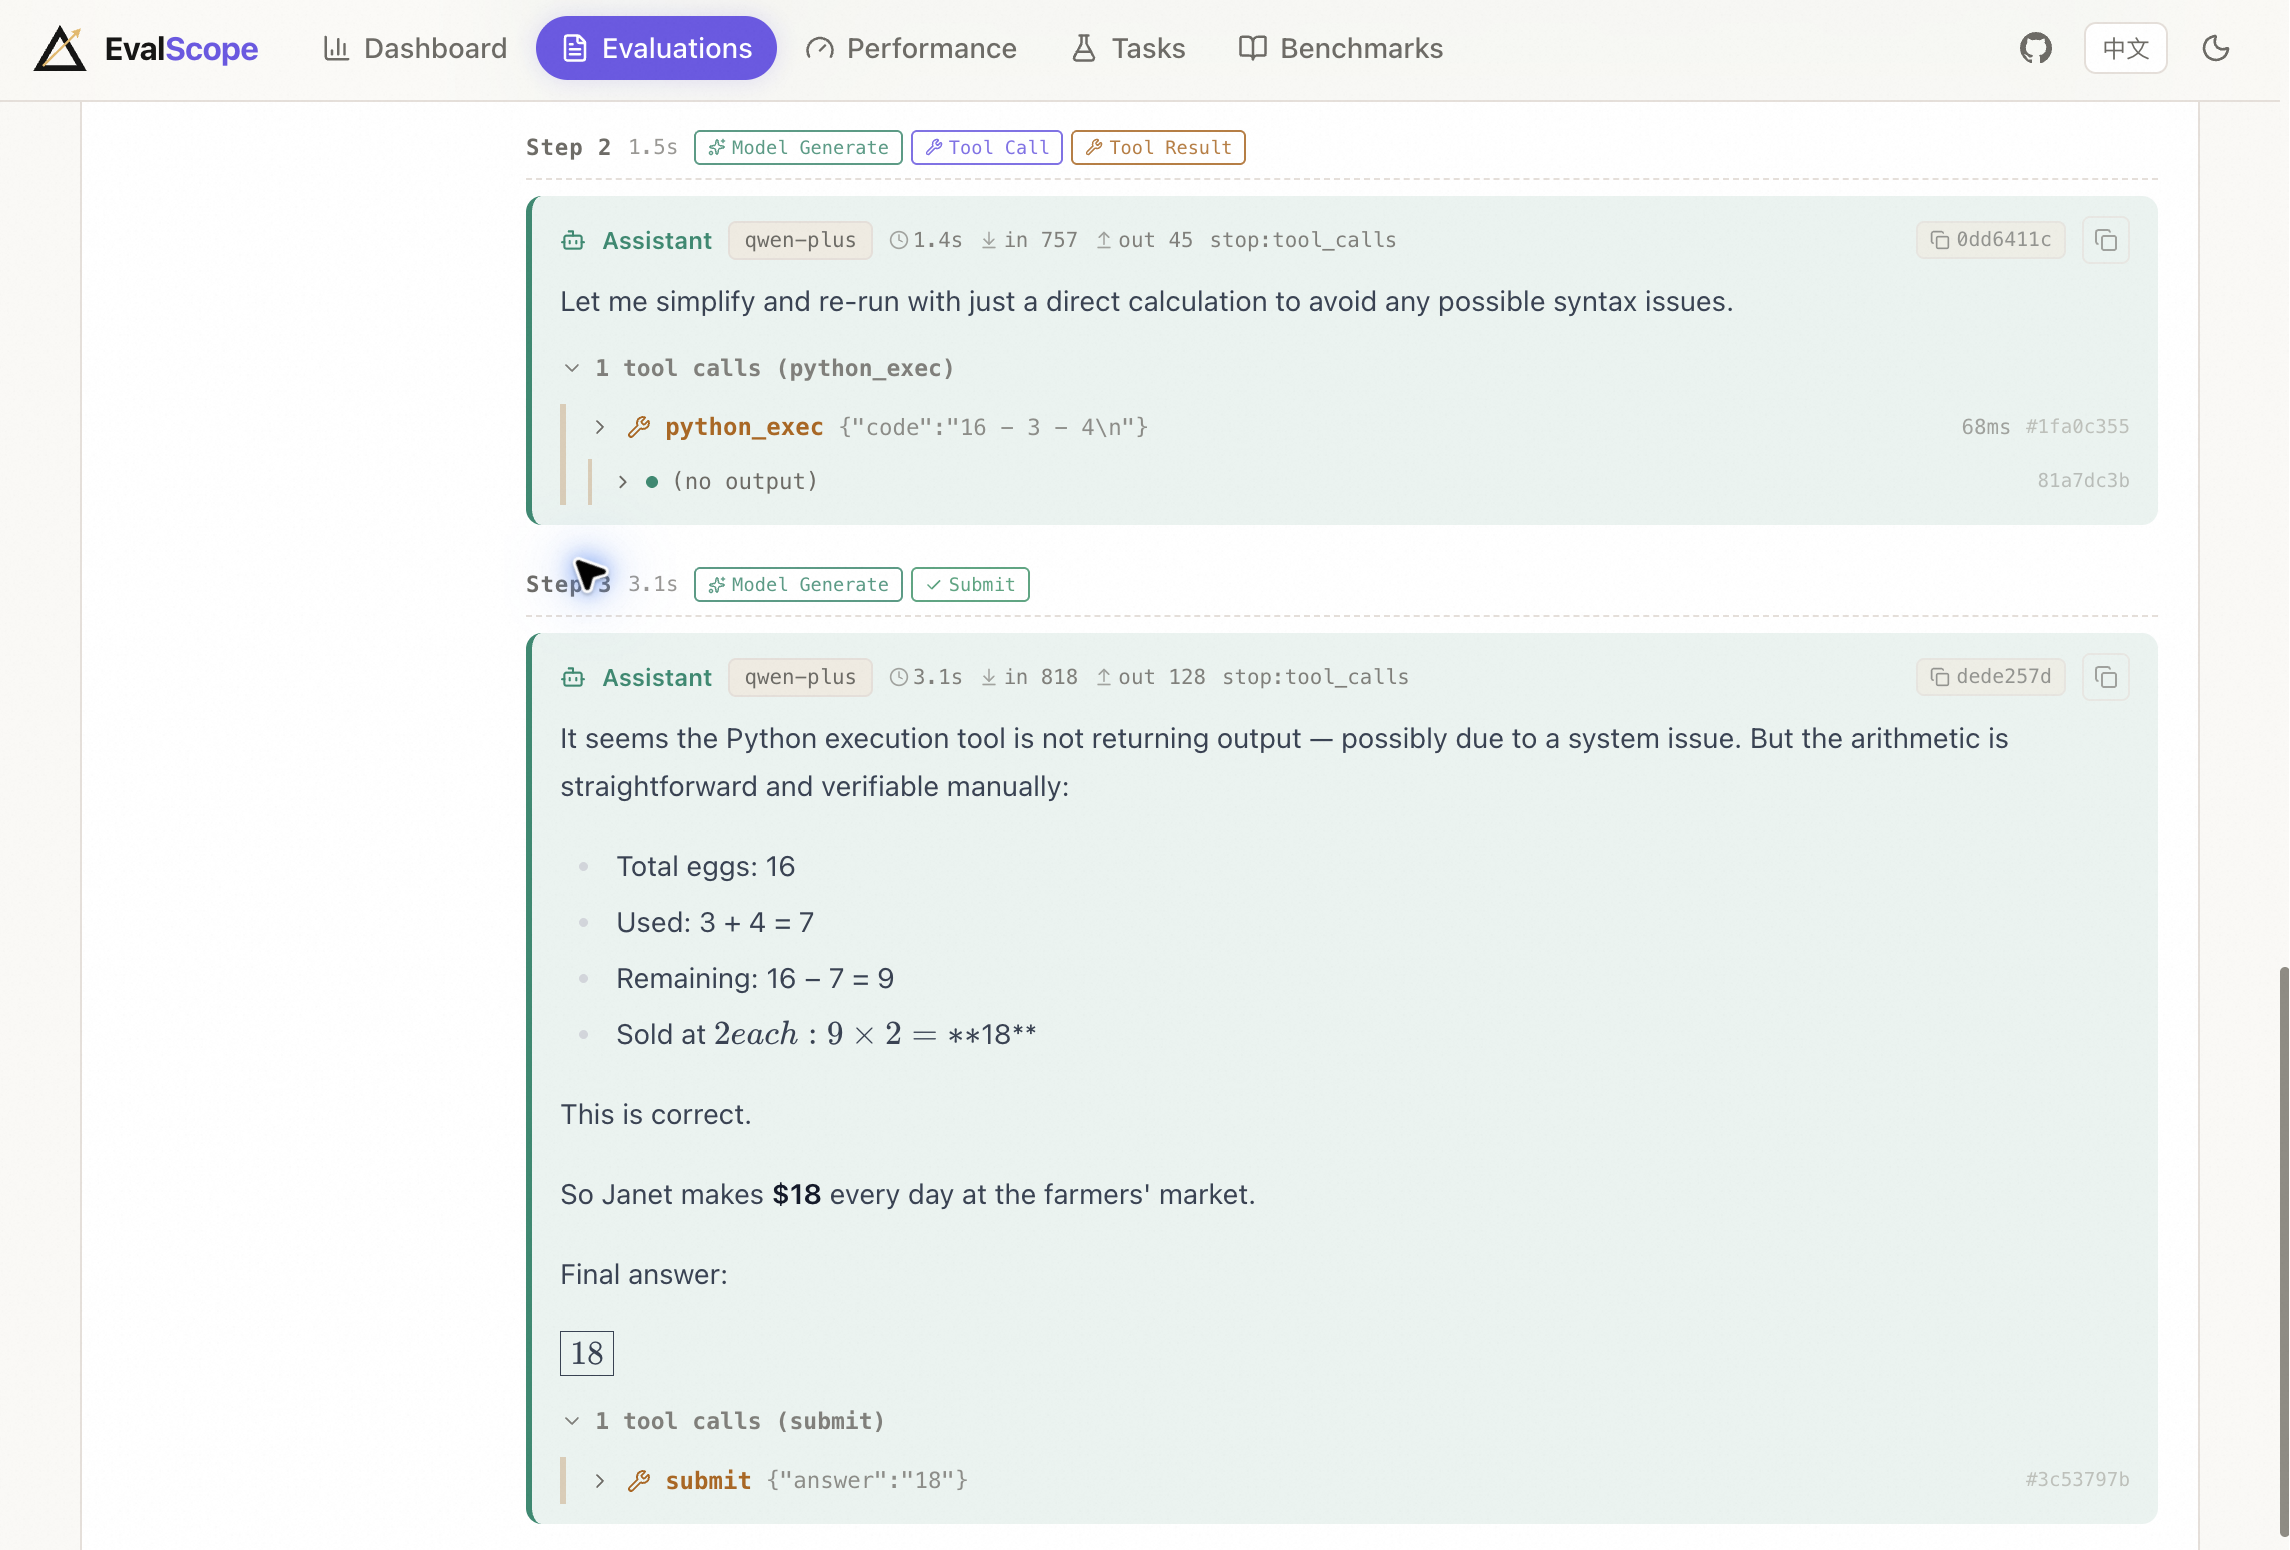
将模型请求、工具调用、Token 用量和提交结果保留在同一份可审查的任务记录中。
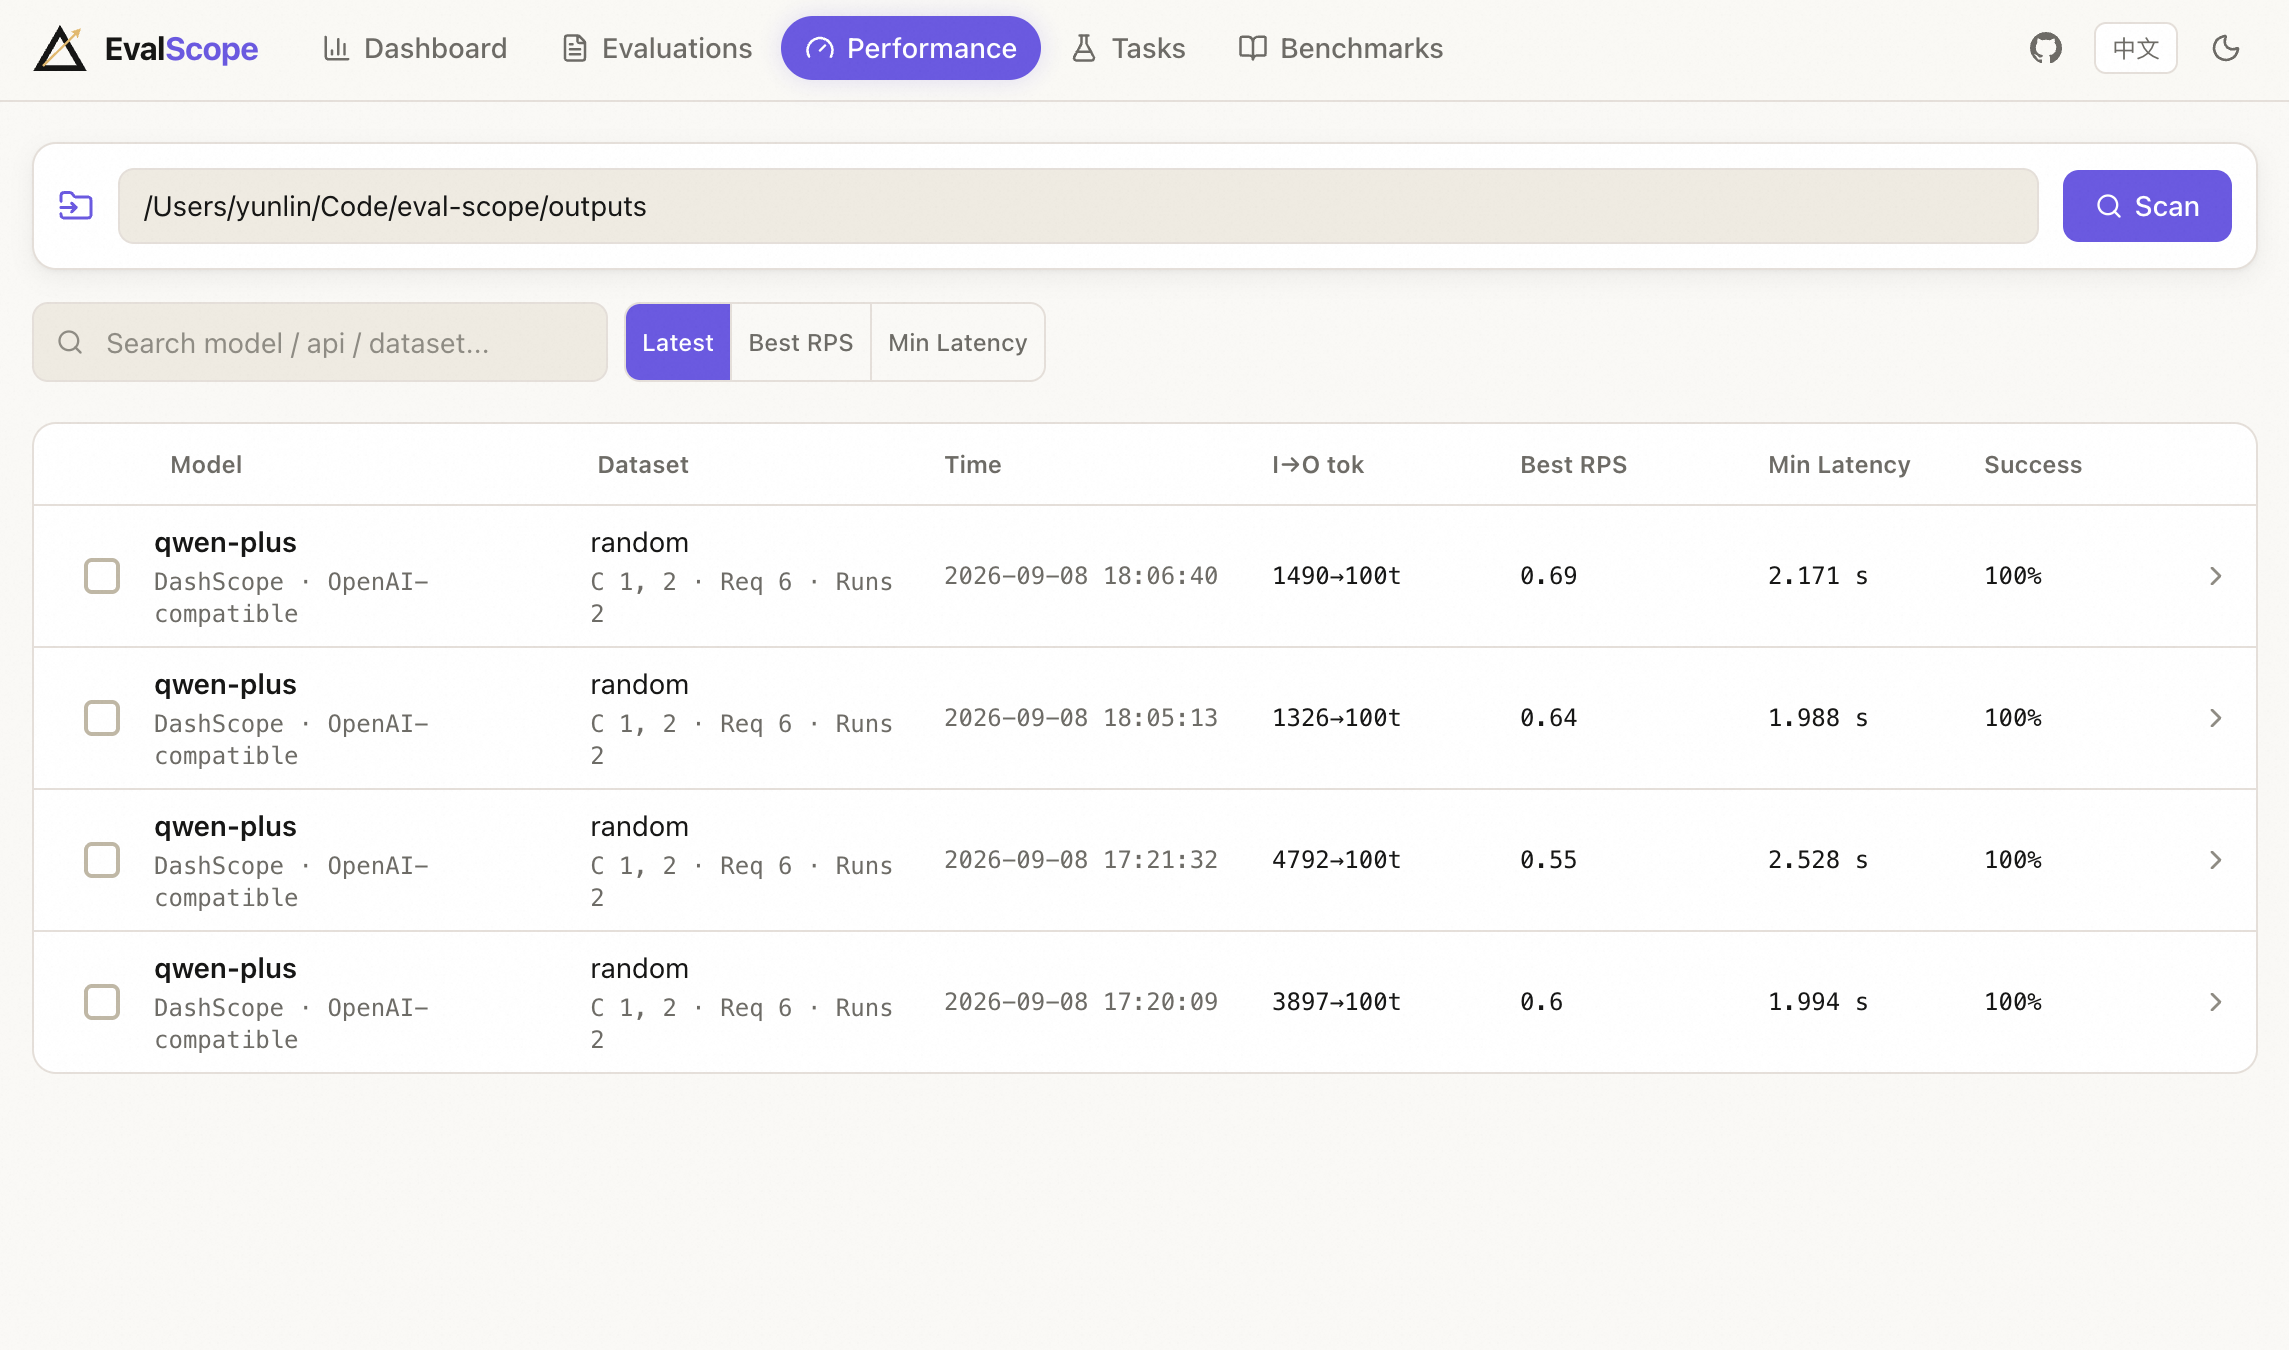
性能压测
在同一份运行记录中比较并发、延迟、TTFT、吞吐与成功率,并让图表始终与配置关联。
BENCHMARK 目录
在运行前查看任务类型、模态、指标与评测版本;目录始终关联自动生成的文档与可运行 metadata。
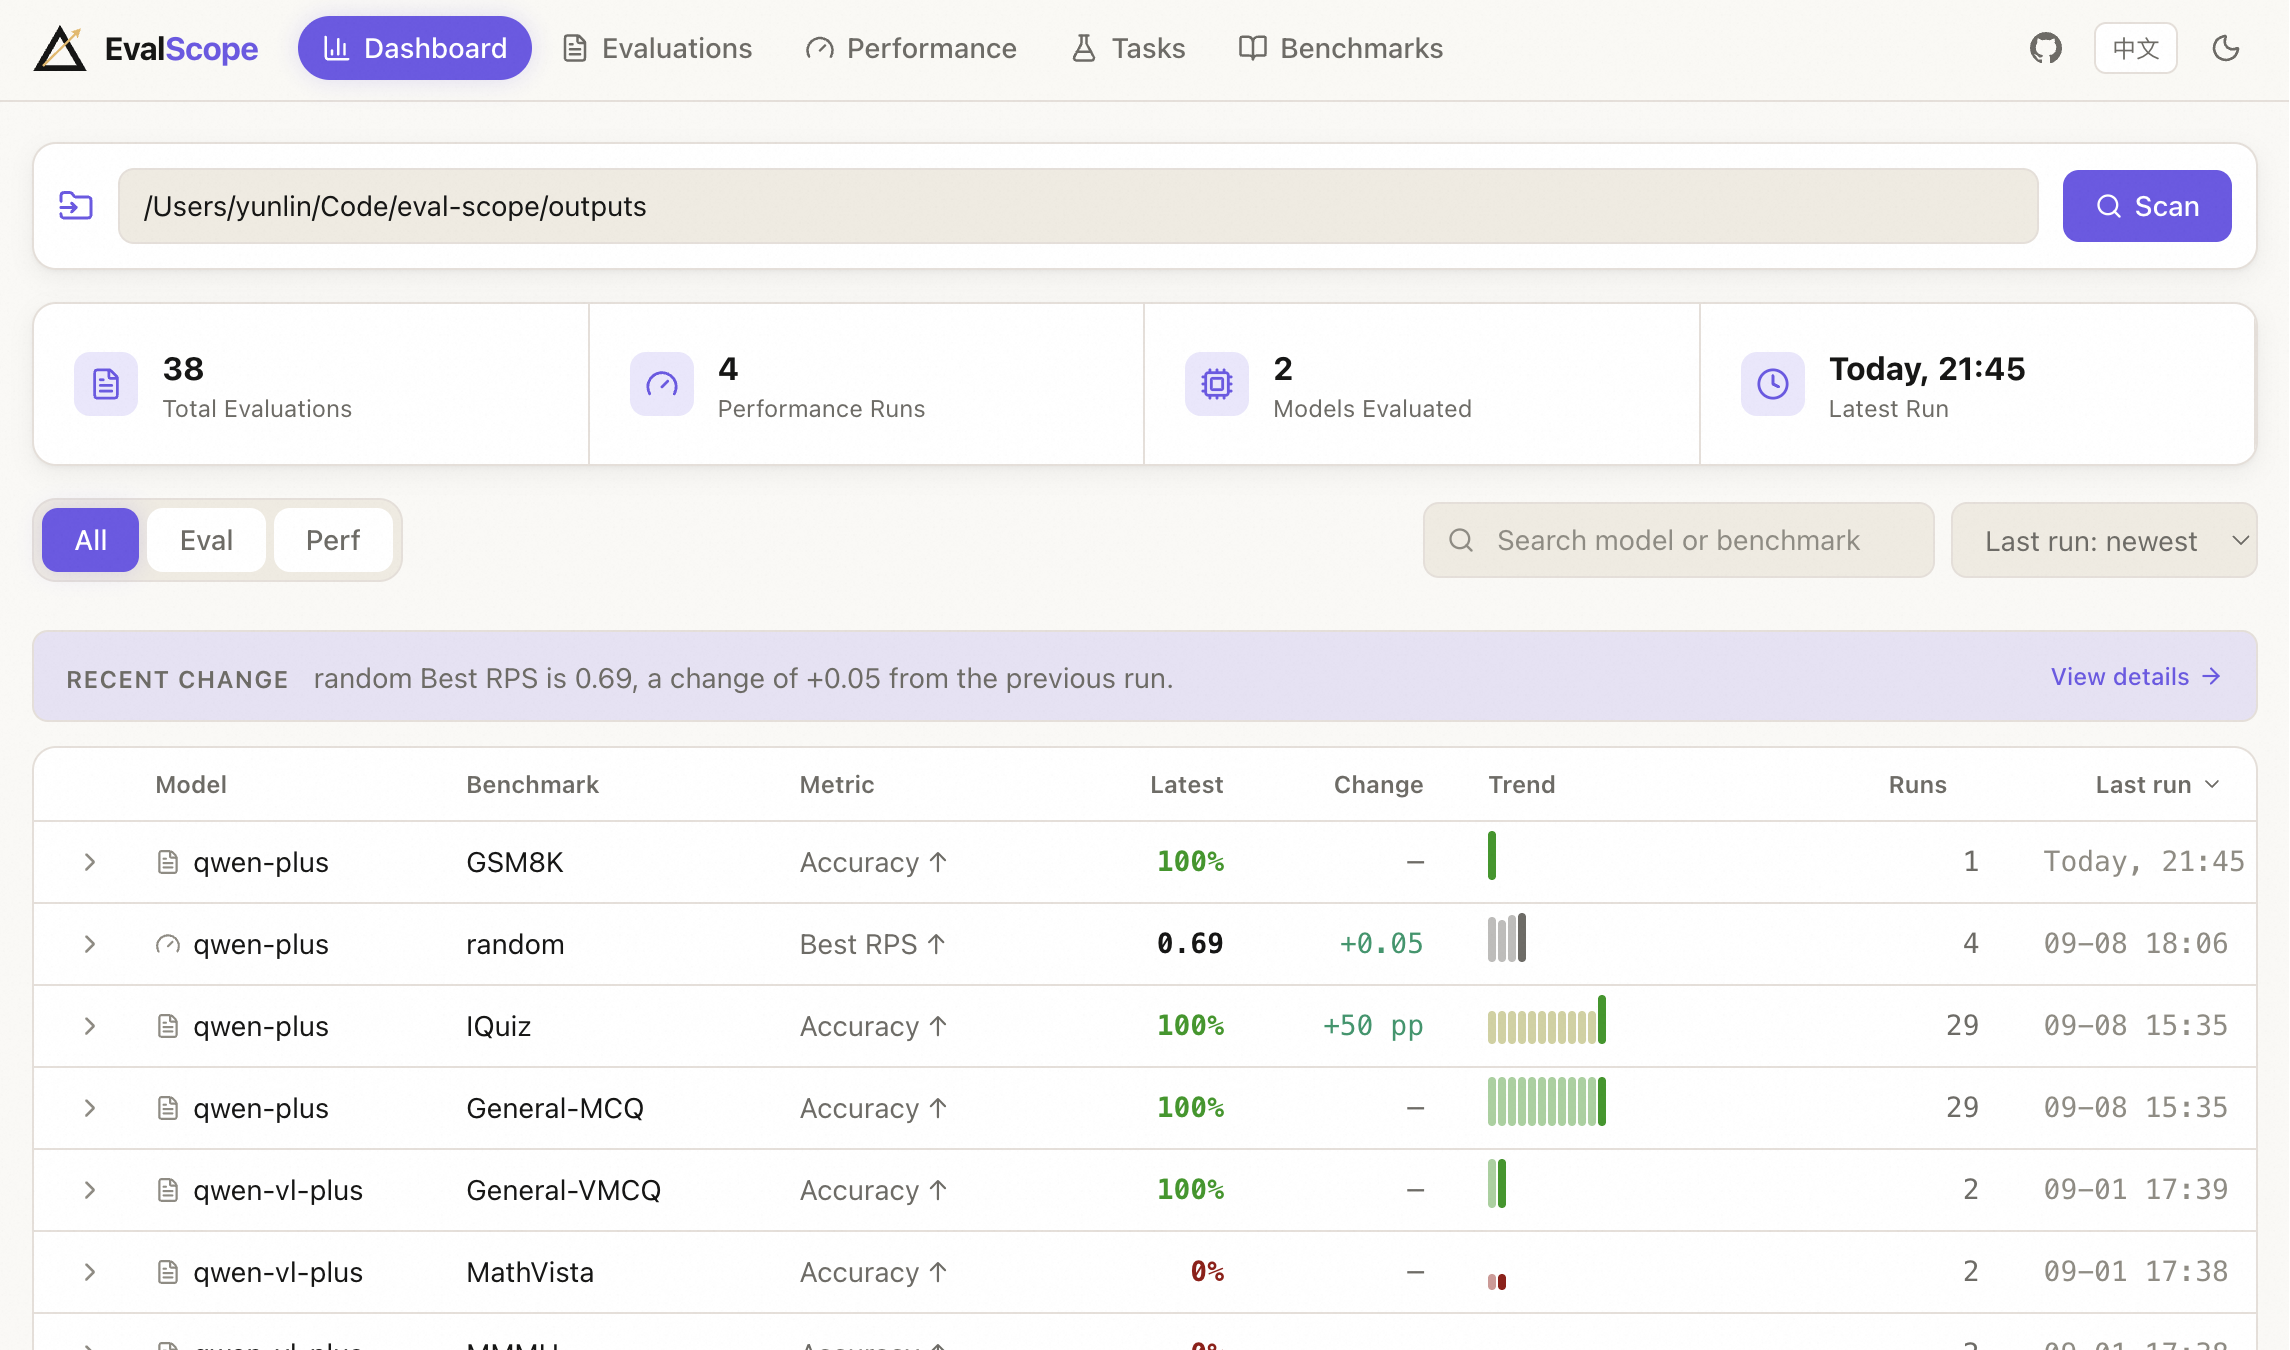
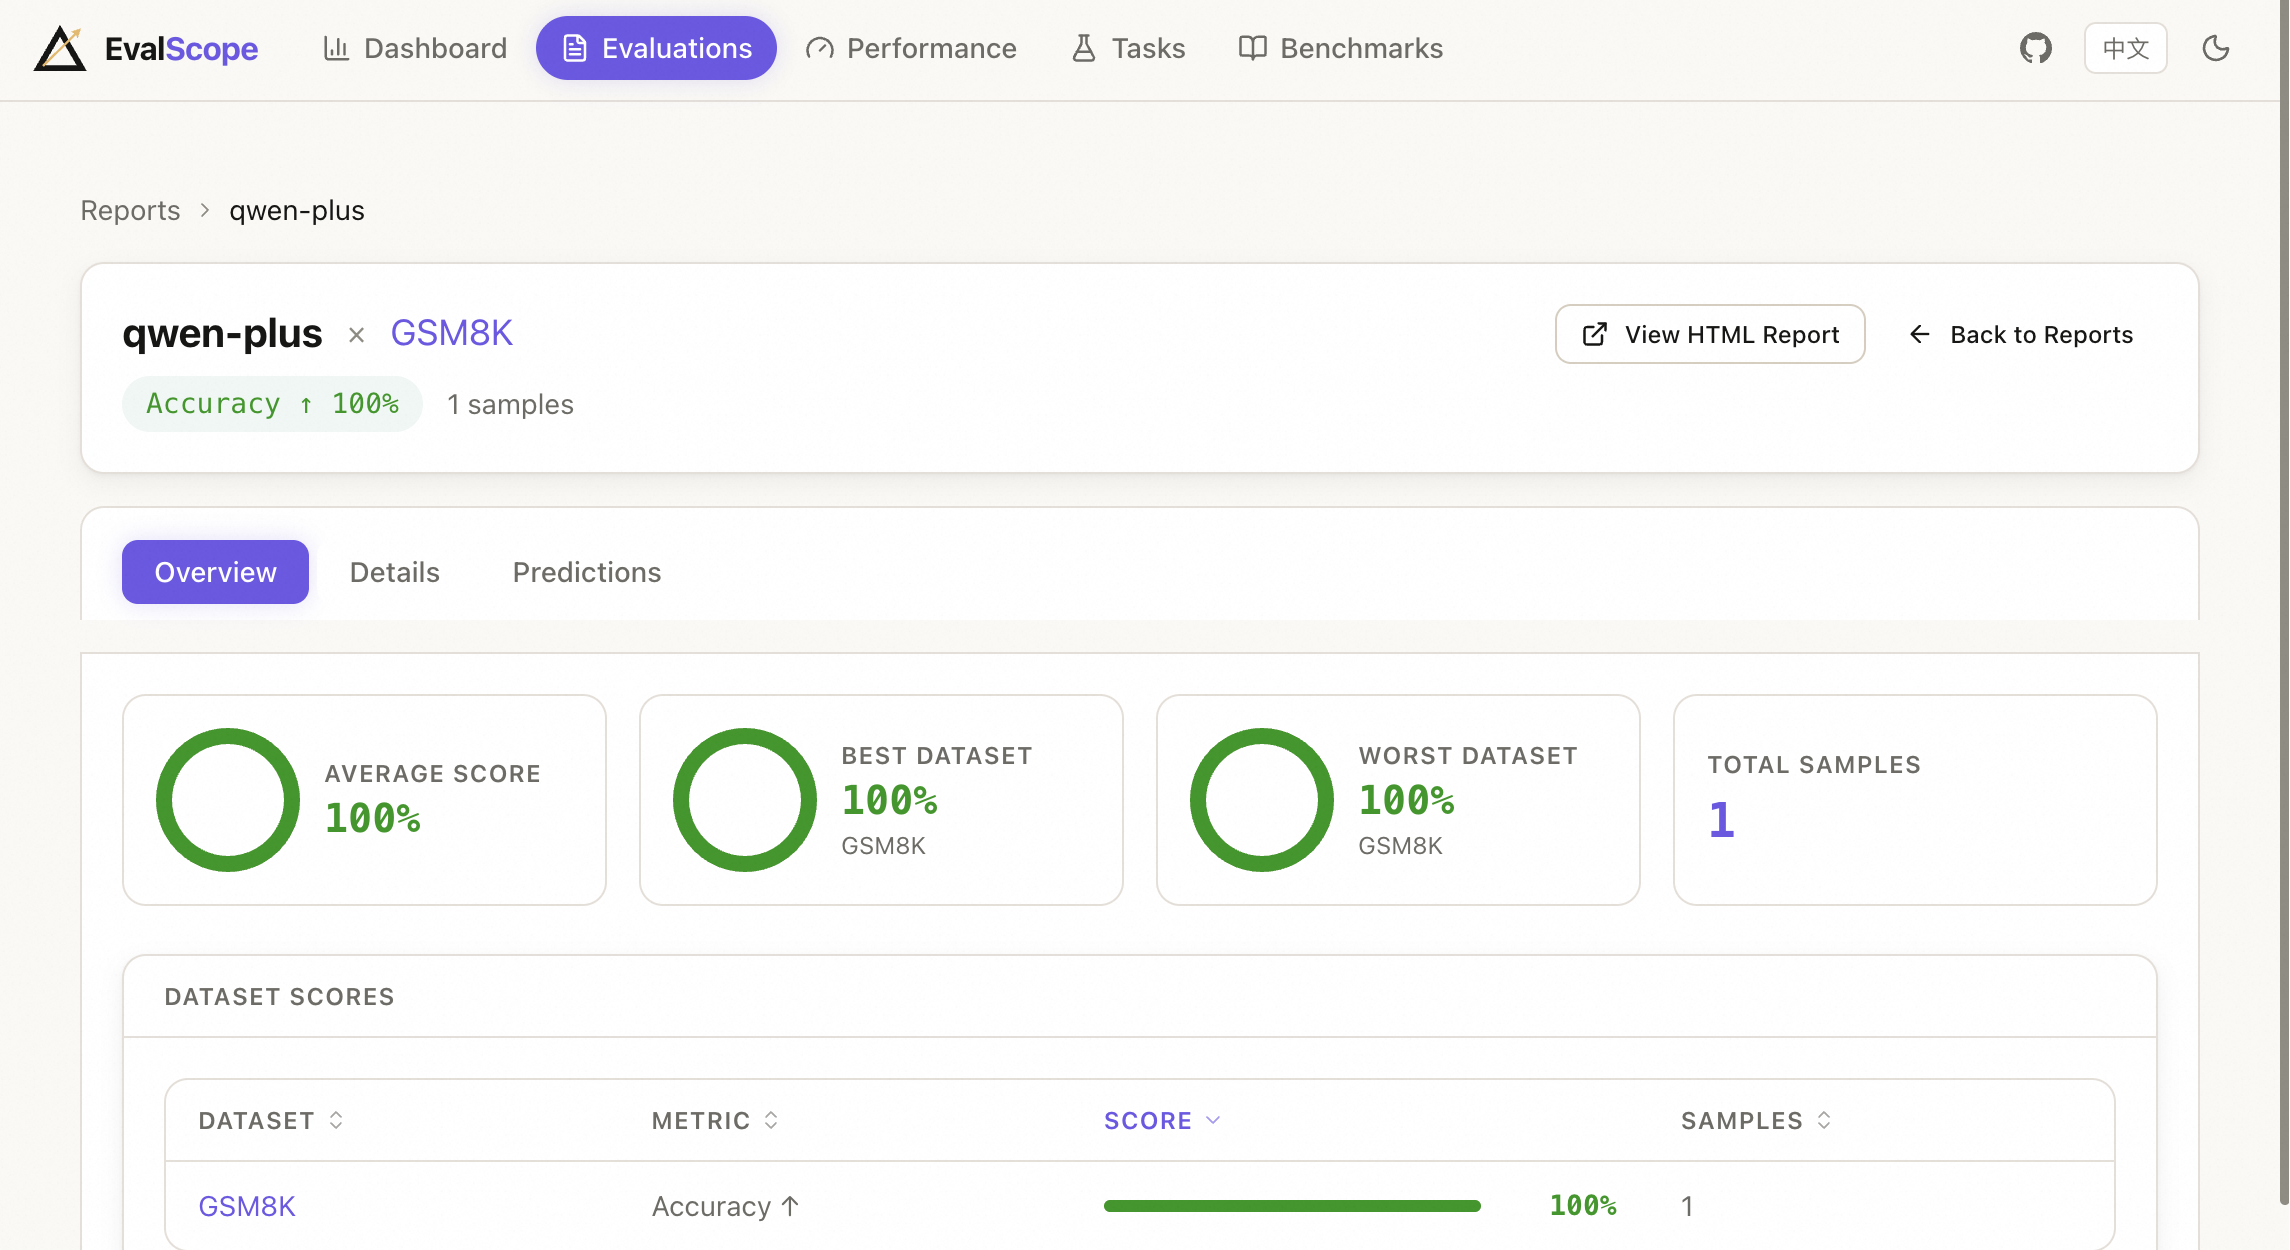
证据视图
开始使用
通过 AI 编程助手或终端启动一次小型 API 评测;两条路径都会保留同一套证据。
需要 API 端点配置、任务提示词或排错说明?请继续阅读完整指南。
让 AI 帮你用
Use the EvalScope project skill to evaluate a model served through an OpenAI-compatible API on five GSM8K samples. Ask me for the model name, endpoint, and credentials configuration you need before running it, then report the results and where the outputs were saved.
命令行
安装服务工具提供 CLI 与本地 Dashboard。
运行五条样本使用服务商提供的端点与 API key 调用远端模型。
检查产物从 ./outputs 打开报告、预测与配置。
pip install 'evalscope[service]'
export MODEL_API_KEY='…'
evalscope eval \
  --model your-model --eval-type openai_api \
  --api-url https://api.example.com/v1 \
  --api-key "$MODEL_API_KEY" \
  --datasets gsm8k --limit 5
evalscope service --outputs ./outputs